
How Search Engines Discover and Index Web Pages

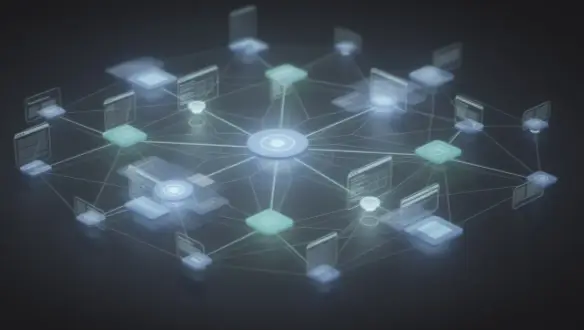
Search engines start with curated seeds like sitemaps, RSS feeds, and well-linked pages, then traverse the web graph to bootstrap discovery. Crawlers allocate budgets using data-driven heuristics, prioritizing link-rich domains and fresher content. Discovered pages are parsed, structured, and subjected to fidelity and accessibility checks before indexing. Quality and freshness signals influence ranking placement, while efficient feature extraction and normalization convert pages into durable results. The path from discovery to results hinges on scalable, repeatable processes that invite closer scrutiny.
Discovery Fundamentals: How Crawlers Find Web Pages
Crawlers, or web robots, begin discovery by identifying an initial set of starting points—typically sitemaps, RSS feeds, and well-linked pages—from which to traverse the web graph. The process measures crawling cadence and prioritizes link-rich domains.
Data-driven heuristics assess sitemap usefulness, guiding crawl queues, latency targets, and freshness signals, ensuring scalable coverage while maintaining disciplined, methodical resource allocation for sustainable discovery.
Indexing Criteria: How Search Engines Decide What to Index
Indexing criteria determine which discovered pages are retained in the search index based on measurable signals of value and quality.
The methodology quantifies relevance through content fidelity, structural integrity, and access reliability.
Signals are weighted, normalized, and audited against crawl budget constraints, prioritizing durable assets.
Space remains allocated to high-impact pages, while redundant or low-signal resources are deprioritized or excluded to preserve index health.
See also: timesnewsmedia
Freshness and Quality Signals: How They Shape Indexing
Freshness and quality signals complement the prior discussion of indexing criteria by capturing how recently content changes and how well it adheres to sustained quality standards influence indexing outcomes.
In a data-driven frame, freshness signals quantify update recency and cadence, while quality signals assess accuracy, depth, and consistency.
Combined, they modulate crawl priorities and indexing confidence, guiding discovery and long-term visibility.
From Discovery to Ranking: How Pages Move to Search Results and How to Optimize
The journey from discovery to ranking hinges on the systematic transformation of web pages from initial exposure to evaluated relevance for search results. Pages pass through crawling, indexing, and feature extraction, where signals are quantified to determine ranking. Crawling efficiency influences timely coverage, while crawl budgets constrain fetches. Optimizations focus on crawlability, structured data, and stable signals to improve relevance and accessibility.
Frequently Asked Questions
What Happens After a Page Is Crawled but Not Indexed?
After crawling, a page may await the indexing pipeline; post crawl indexing issues restrict content eligibility, delaying or preventing indexing. The system logs signals, retries, and prioritizes pages based on quality signals, crawl budget, and editorial policies for discovery.
How Do Search Engines Handle Duplicate Content?
Duplicate content is managed through canonicalization rules, enabling engines to select a primary version; variants are de-emphasized or ignored. The approach is data-driven, methodical, and aims to preserve index quality while supporting user freedom and exploration.
Do Images and Videos Get Indexed the Same as Text?
Images indexing and video SEO are not identical to text; engines index metadata, transcripts, and alt content, with distinct ranking signals. They process visual signals separately, using visual features and schema, alongside traditional crawling and indexing workflows.
How Often Do Search Engines Re-Crawl Sites?
Crawl frequency varies by site, but search engines generally re-crawl based on site updates, crawl budget, and change velocity; high-velocity sites see frequent recrawls, while static pages experience longer intervals for crawl frequency and timely indexing of site updates.
Can You Influence Crawl Budget on a Large Site?
Yes, influence is possible with careful techniques. Infinite crawl budget is unlikely, but budget optimization strategies can extend coverage on large sites, prioritizing critical pages. The approach remains data-driven, methodical, and aimed at scalable, freedom-seeking outcomes.
Conclusion
Conclusion (75 words):
Search engines convert discovered pages into indexable resources through a data-driven pipeline that emphasizes provenance, fidelity, and accessibility. Crawlers leverage starting points and the web graph to maximize coverage while budgets and freshness targets guide prioritization. Indexing relies on content quality, structure, and reliable delivery signals, producing durable entries for ranking. An illuminating statistic: pages with fresh, well-structured metadata see up to a 2–3× higher indexing speed, illustrating the tangible impact of signal quality on discovery efficiency.
One Comment